Fashion Catalog VQA - Vision-Language Model
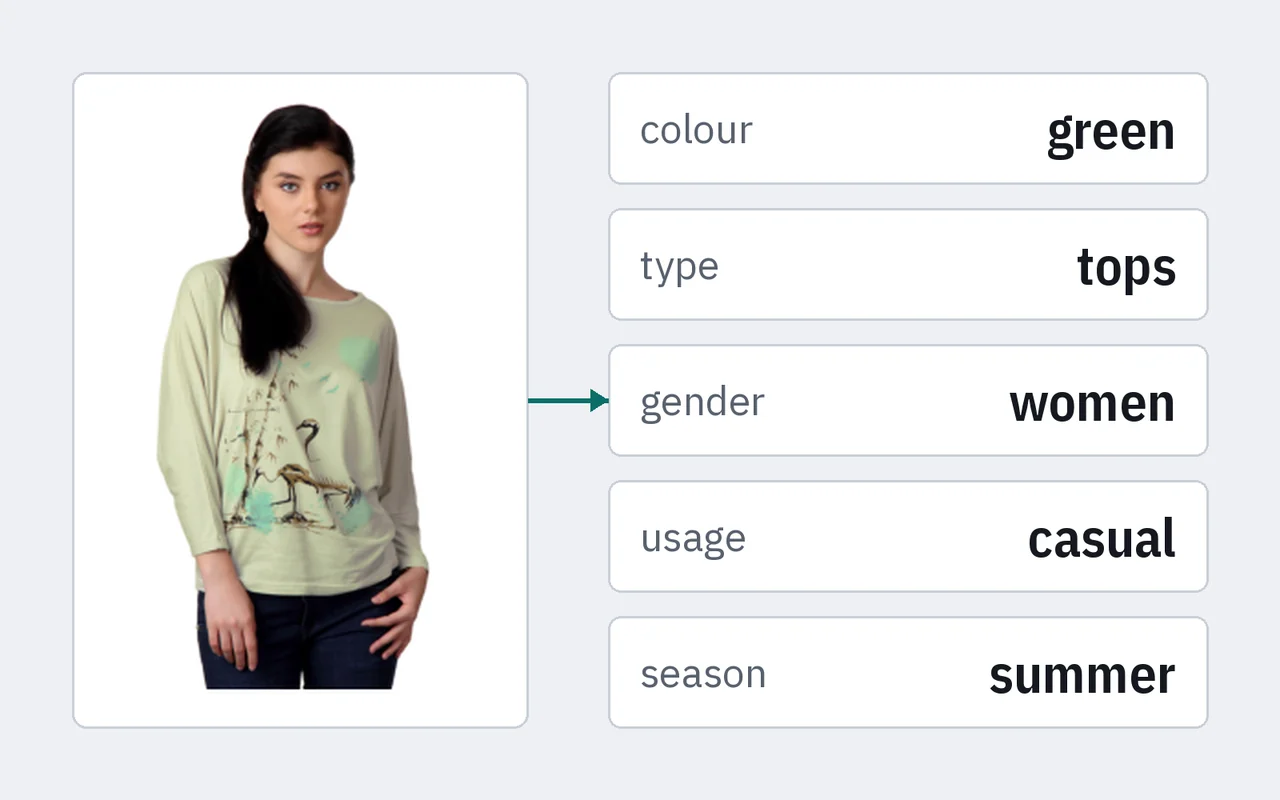
Vision-language model (Qwen2-VL-2B fine-tuned with LoRA) that looks at a fashion product photo and answers in catalog language: color, article type, category, gender, usage, season and a one-line description. Raises exact-match accuracy from 52% (zero-shot) to 90% on held-out products, and includes an inference toolkit for product sheets, top-k confidence, listing audits and batch auto-tagging on a single T4 GPU.
- VLM
- Qwen2-VL
- LoRA
- PyTorch
- Hugging Face